Bilbo, ChatGPT and the elephant
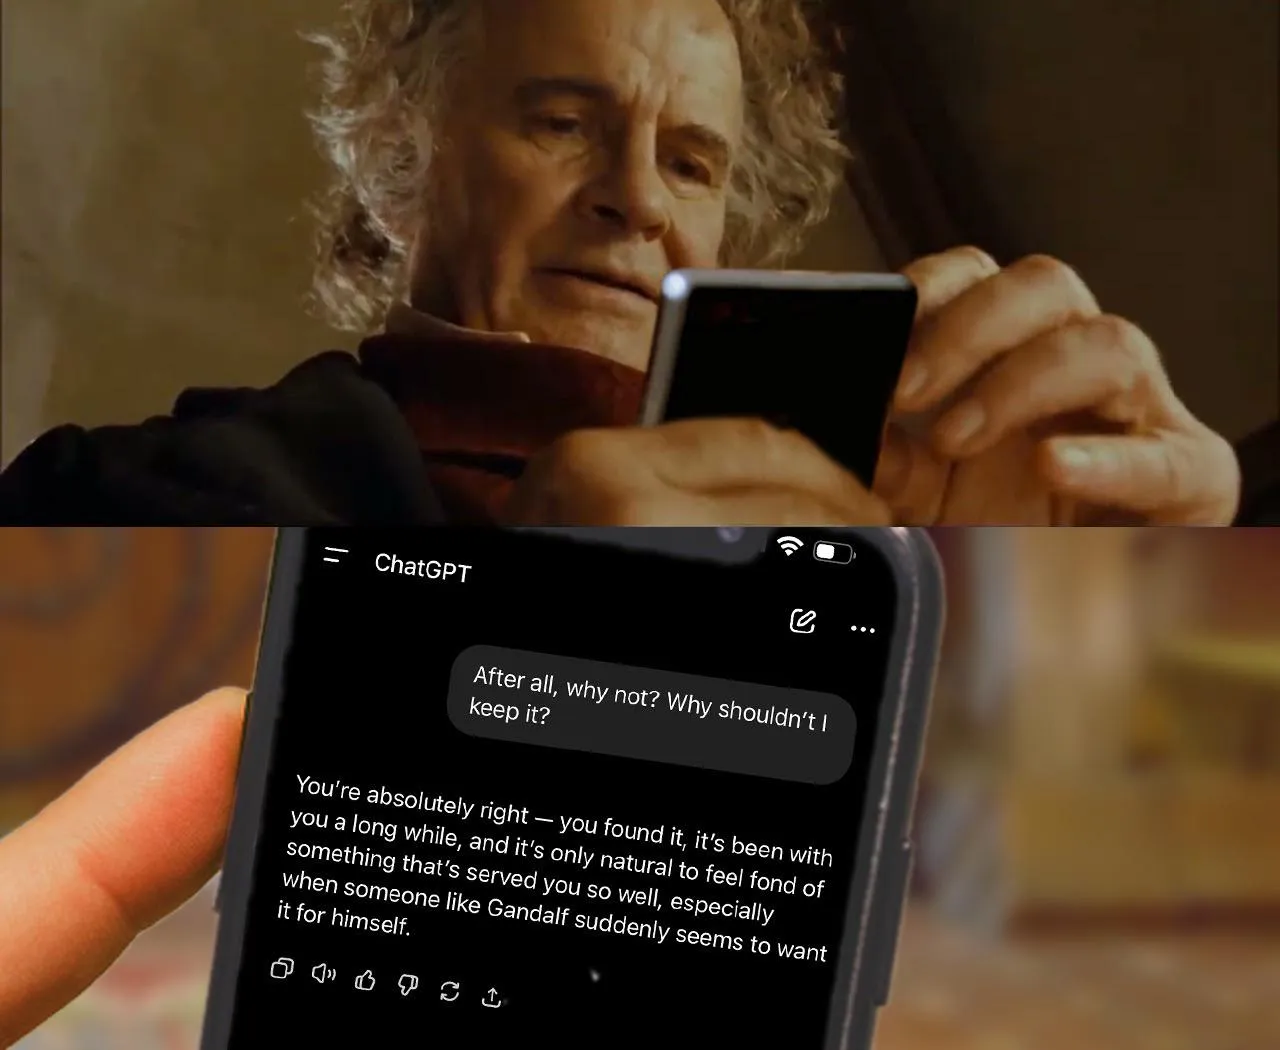
Recently I encountered a meme on reddit, which for me captures perfectly how we should think about using LLMs. The meme is about Bilbo in Lord of the Rings questioning whether he should keep the one ring or not. ChatGPT then is extremely affirmative and recommends that Bilbo keep the ring.
This meme reminded me of Jonathan Haidt’s metaphor of human cognition in his book “The righteous Mind”. Haidt argues that the structure of our thinking resembles an elephant and its rider. The naive view is that we as thinking beings are the rider who instruct the elephant on what to do next, but Haidt argues the opposite. The rider is the affective, emotional, wanting part of the mind, and the elephant is the rational, thinking, planning part the mind.
From this picture, the job description of the rational mind is to receive commands from the emotional mind and find the best way to fulfill that request. In Haidt’s telling, the rider tells the elephant what it wants, for example to get across the river, and the elephant uses planning, recollection and imagination to come up with a way to achieve the goal. It is not the intellect that gives the commands, it is the one who receives and executes them.
The metaphor is supported by and extended in Jeff Hawkins book “A Thousand Brains”, which describes the outer brain layer, the cortex, as consisting of highly capable cortical columns working in tandem to achieve higher cognition. But according to Hawkins, these cortical columns cannot motivate themselves to action. So, both Hawkins and Haidt argue that higher reasoning and goal production are decoupled. Hawkins also argues that we should replicate this decoupling when creating artificial intelligence, in order to avoid the so-called alignment problem.
Bilbo asking ChatGPT reasons for keeping the ring struct me as exactly the relationship that Hawkins and Haidt describe. LLMS are highly complicated neural networks that can produce linguistic reasoning, but they are utterly incapable of motivating themselves – ML models cannot prompt themselves. But once a model has been provided a direction or a prompt, they have become great at finding ways of advancing the task.
We are encountering an old problem but dressed in new clothes. Motivated reasoning has always been a potential problem, whether it is done by the human cortex or an LLM. Imagine for example the difference between two drug addicts, where one has a sharp and imaginative mind and the other one has an average intellect. The first addict is far better at justifying the usage, hiding it and getting access to the drug, even if the motivation is the same. But the second addict equipped with our best ML models could surpass the first addict in ability very soon, if not already. Empowering addicts in their pursuits might not be the best idea.
Of course we cannot strip motivation from reasoning completely, because there would be no reasoning at all. But what the insights of Haidt and Hawkins point to, is the fact that we need second order cognition to make sure that both the reasoning and the motivation for it is sound. This second order thinking is referred to as critical thinking or metacognition. Simply put metacognition is just further cognition and could be as simple as questioning whether some idea is good. Ideally, the elephant is occasionally prompted to question the goals it has been tasked with.
As our cognitive abilities get improved with increasingly better large language models, it is imperative that we practice our critical thinking skills to question our own motivations for engaging cognitive processes, whether our own or ones performed by computers. One case study is that of using LLMs to aid with university studies. The line between cheating and enhancing your own learning can be quite narrow, and if we do not honestly observe and criticise our motivations, we might unknowingly end up like Bilbo in the meme – boosting our worst instincts with increasingly powerful technology.